


Hugging Face calls for standards in embedded AI evaluations
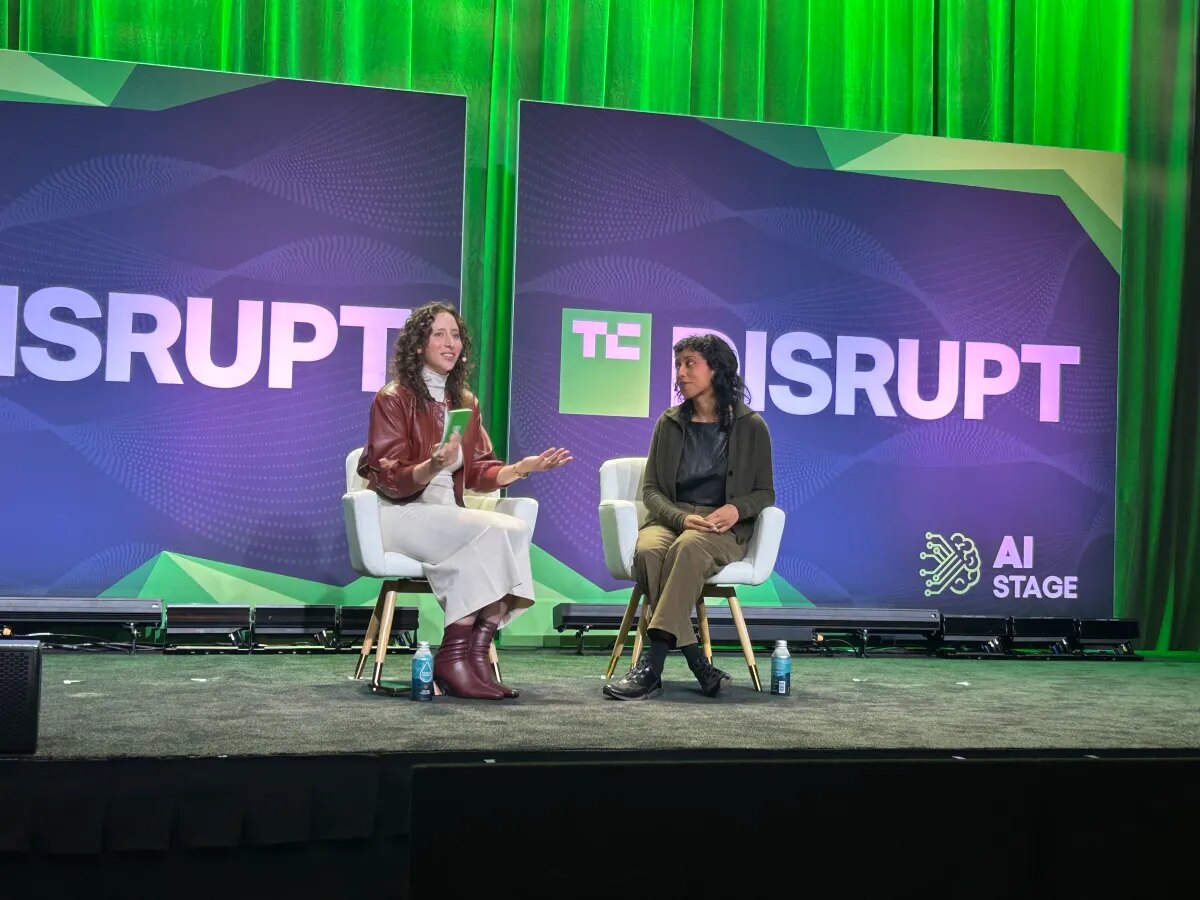
Hugging Face chief policy officer Irene Solaiman has warned that embedded AI evaluators will not provide an easy answer to model-safety oversight without stronger, shared standards. Speaking at TechCrunch Disrupt, she said the industry’s benchmarking methods remain an evolving science, even as AI labs increasingly rely on evaluations to demonstrate model performance and safety.
The central question is not simply whether a benchmark produces a result, but whether that result can be reproduced and meaningfully compared with other evaluations. Solaiman said access to the underlying model is an important part of reproducibility, and that open weights have a significant role in enabling such scrutiny.
Reproducibility remains central to trust
AI labs have placed considerable weight on benchmarks intended to compare one product with another. Solaiman cautioned that “trust” is a demanding term in this setting: confidence in an evaluation depends in part on whether others can reproduce its results and have the necessary access to the model.
She also said the sector does not yet know how to compare evaluations meaningfully across the growing number of tests. In her view, evaluations can lose effectiveness relatively quickly, while the ecosystem needed to sustain and improve them is not yet sufficiently developed.
Embedded evaluators need clearer qualifications
The idea of placing ostensibly neutral third-party evaluators inside AI organisations has gained attention as labs respond to safety incidents and concerns about possible harms from their technology. Rather than active government regulation to identify and mitigate those concerns, labs have promoted third-party evaluation as an alternative approach.
Solaiman said there is now strong demand for an embedded evaluator ecosystem, but the qualifications for judging whether an evaluator is effective across different tasks require much more standardisation. The issue has been highlighted by Anthropic’s decision to hire Accenture as its first evaluator, which drew criticism from observers who questioned the consulting firm’s suitability for the role.
From model tests to system-level assessment
Evaluation is also moving beyond the model alone. Solaiman said assessments increasingly need to examine the whole system around a model, including the harness and the agent. The harness is the tool through which a user accesses a model, and it can materially affect the outcome: a weaker model paired with a better harness may outperform a frontier model.
Agentic evaluations are particularly difficult and expensive, she said. The industry has more evaluations for models than for harnesses, although work is progressing on assessments of the holistic agent because that is where many users derive value.
For businesses using benchmark results in procurement, deployment, or governance decisions, the practical implication is to assess what was tested, whether the findings can be reproduced, and how the surrounding harness and agent shaped the result rather than treating a single score as a complete judgment.